For manufacturers, an unexpected production stoppage is rarely just an engineering problem. Delayed orders, idle staff, wasted materials and disrupted delivery schedules can quickly turn a technical fault into a wider business challenge. Yet many factories still struggle to identify the warning signs that appear before equipment fails.
The answer is not necessarily to replace machinery or invest in an entirely new production line. A more realistic starting point is to make better use of the operational information that existing equipment already produces. When that information is accessible, reliable and placed in context, it can help businesses spot emerging issues and make more informed maintenance decisions.
The Hidden Business Cost of Unplanned Stoppages
Downtime can have consequences far beyond the affected machine. If one critical asset stops, upstream processes may have to slow while downstream teams wait for materials. Maintenance resources are diverted, production schedules change, and customer commitments become harder to meet.
The financial impact varies by site and process, so there is no universal cost per hour. A manufacturer producing short, high-volume runs will experience disruption differently from a facility operating continuous processes. What they have in common is a need to understand where interruptions happen, why they happen and which problems are worth addressing first.
Without dependable data, those decisions often rely on incomplete shift reports, manual spreadsheets or the recollections of experienced staff. Valuable knowledge may exist, but it remains scattered across teams and systems.
Turning Existing Equipment Data Into Useful Insight
Many industrial assets already provide signals such as running status, temperature, pressure, fault codes and cycle times. The challenge is that this information may be held in controllers, supervisory systems or historical databases that do not communicate easily with the applications used by managers and maintenance teams.
Connecting these sources can provide a more consistent picture of asset performance. Rather than simply knowing that a machine stopped, teams may be able to see how operating conditions changed beforehand, how often similar interruptions occur and whether the same failure pattern appears across different shifts.
This does not make every breakdown predictable. Some faults happen without useful advance warning, and poor-quality measurements can lead to misleading conclusions. However, establishing a trustworthy operational record is a practical first step towards more systematic maintenance.
Why Older Machinery Still Has a Role
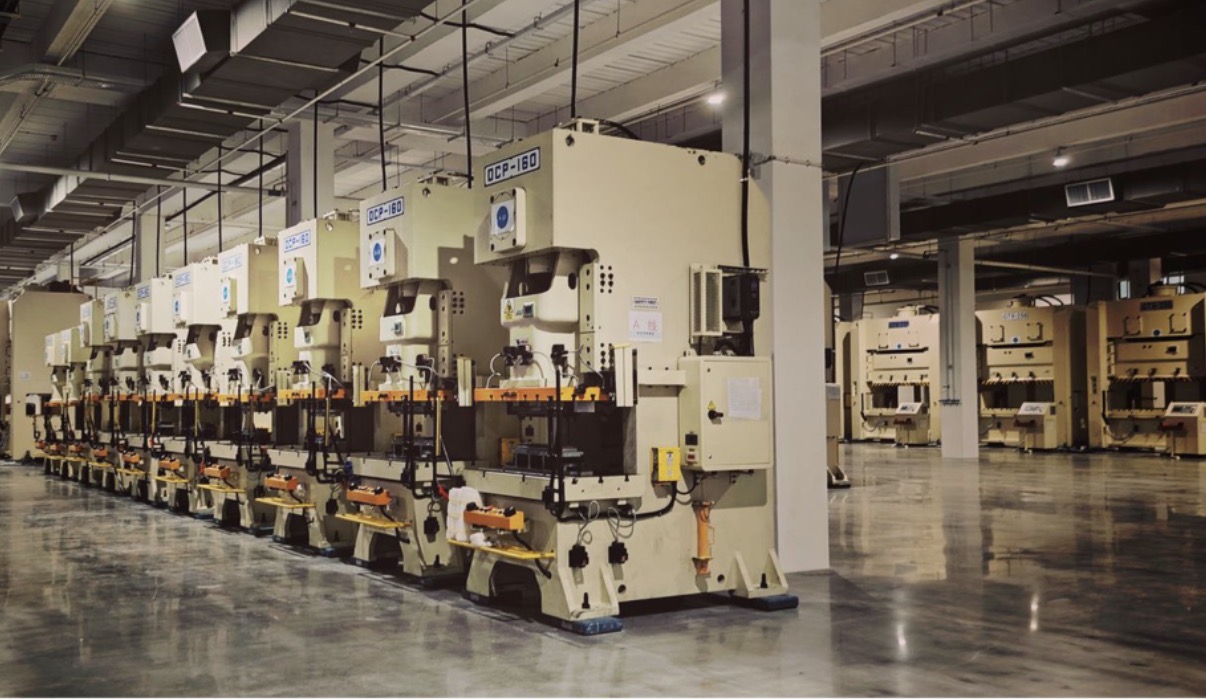
Modernisation does not always require a complete equipment replacement programme. Many factories operate a mixture of long-serving machines and newer automated systems, often introduced years apart. The machinery may remain productive, even if its communications technology differs from that used elsewhere on site.
Businesses can benefit from assessing how these systems exchange information before considering major capital expenditure. Specialist industrial IT services can help organisations review existing infrastructure, identify compatibility constraints and plan connections between operational equipment and higher-level systems.
That work is particularly important when legacy protocols must coexist with newer applications. The priority should be maintaining stable production while allowing appropriate information to reach the people and systems that need it.
From Reactive Repairs to Better Maintenance Planning
A reactive maintenance approach usually begins when something has already gone wrong. Engineers investigate the fault, source components and restore operation while production absorbs the disruption. Planned maintenance can reduce that uncertainty, but fixed service intervals may not always reflect how equipment is actually being used.
Access to consistent operational data creates opportunities for condition-based decisions. For example, repeated temperature excursions, rising vibration readings or changes in cycle times may justify further inspection. Maintenance teams can combine those signals with asset history, operator observations and engineering judgement to decide when action is appropriate.
The objective is not to hand responsibility to a dashboard. It is to provide employees with better evidence, helping them distinguish isolated anomalies from recurring problems and prioritise interventions according to operational risk.
Making Data Available Without Compromising Production
For business leaders, connecting machines to analytics systems may sound straightforward. In practice, industrial environments require more care than ordinary office networks. Control systems often operate continuously and may not tolerate unexpected traffic, untested changes or unrestricted remote access.
A managed integration layer can help move selected information from industrial systems into reporting, historian or maintenance applications without requiring every new application to communicate directly with the control equipment. Depending on the architecture, industrial middleware can translate between protocols, aggregate information and provide controlled pathways for operational data.
This is where software designed for industrial data integration may be relevant. Such tools should be evaluated against the site’s actual protocols, security boundaries, reliability needs and support arrangements rather than chosen solely for their list of features.
Segmentation, access controls, testing and recovery planning remain essential. Better visibility should never come at the expense of the availability and safety of the equipment supplying the data.
Start With One Measurable Operational Problem
The most useful improvements often begin with a modest question: which production interruptions cause the greatest disruption, and what information would help the team respond sooner? A business might start by monitoring a bottleneck machine, comparing stoppage reasons between shifts or improving the data feeding an existing maintenance system.
Before investing, teams should agree how success will be measured. Relevant indicators might include time spent investigating faults, repeat stoppage frequency, maintenance response time or the completeness of incident records. Clear definitions matter, otherwise apparent improvements may reflect changes in reporting rather than operations.
A small pilot also provides a chance to check signal quality, staff requirements and the effect of integration on existing systems. Once the approach proves useful, it can be extended to other equipment or sites with less guesswork.
A More Resilient Approach to Manufacturing
Industrial businesses do not need more data for its own sake. They need information that helps people protect production, plan maintenance and make sound investment decisions. Connecting existing equipment to the right systems can support those goals, provided the project starts with a genuine operational need.
For manufacturers balancing cost pressures with demanding delivery schedules, the opportunity is to reduce uncertainty rather than promise an end to breakdowns. Better factory data will not eliminate every interruption, but it can make the causes of disruption easier to understand and the next decision easier to justify.